

Almost every AI-and-design-systems demo I’ve done starts from an unfair advantage. The codebase already exists. The framework is chosen, the styling method is settled, the token architecture is in place. The AI has dozens of examples to pattern-match against, so of course it produces something reasonable. It’s reading the room because the room is already furnished.
I wanted to see what happens when the room is empty.
So I started with a directory called “eventz-design-system.” No markdown files, no package.json, no directories, nothing. On the Figma side, a fresh demo file with a button component set I’d just run through FigmaLint. That’s the whole starting position: a blank folder and a design file.
Start with your mise en place
Before any cooking happens, a good kitchen has everything in its place. Same idea here. Before I ask the AI to build anything, I want it to know exactly what we’re working with: the framework, the styling method, the icon set, and most importantly, where the tokens come from.
So the first move isn’t “build me a button.” It’s establishing context. I asked the Figma Console MCP for a status check, just to confirm the client was actually aware of the Eventz Design System file. Confirmation first. Then I gave it the architecture in one shot:
React-based application
Latest version of Storybook via npm
Lucide icon set (the buttons have optional leading and trailing icons)
CSS custom properties with CSS Modules for styling
Export tokens from the live Figma file using the Figma Console MCP
That last instruction is the one that matters most. I’m not asking the AI to invent a color palette or guess at spacing. I’m pointing it at the source of truth and telling it to pull from there.
Why this architecture
A few of these choices are deliberate, and worth explaining since the Substack crowd asks.
CSS custom properties with CSS Modules keeps the token layer honest. The exported variables live in a master sheet as real CSS properties, and the module files reference them. Nothing gets hardcoded into a component. When a value changes upstream, it changes everywhere downstream, because everything points back to the same set of properties.
The token export uses the DTCG (Design Tokens Community Group) JSON spec. That’s the part I care about. It means the tokens aren’t in some proprietary shape that only this workflow understands. They come out in a community standard, and from that JSON you can generate CSS, CSS-in-JS, Tailwind, whatever you need. The JSON is the canonical layer; the rest is downstream.
And it goes both ways. We added two tools to the Console MCP: an export and an import. Export reads the Figma variables table and writes the tokens out. Import does the reverse. If a value changes in the JSON on the code side, you run the import and it compares the code-side tokens against the Figma variables table, then updates Figma to match. Design-to-code token parity, in both directions. Whichever side moves, the other can catch up.
What it built, and where it got ahead of itself
The plan it came back with was solid: scaffold React with Vite, install Lucide, install Storybook 10, inspect the Events tokens, wire the exported tokens into the app and Storybook, write a README. It ran the figma_get_variables tool to see what was available, then ran the export. It connected 312 variables, light and dark mode, tier one and tier two, all coming straight from the Figma variables table into clean CSS custom properties.
Then it did something I didn’t ask for. Because I happened to have the button selected in Figma, it decided to build the button too 😬.
This is the honest part of the demo. The first-pass button looked fine at a glance, but it wasn’t right. It didn’t actually share the token architecture and properties of the real button in Figma. The Claude Opus 4.7 model, especially running at a higher effort, has a tendency to go above and beyond and fill in gaps with its own assumptions. It was enthusiastic. It was also wrong.
Here’s the fix, and it’s the whole point of working this way. The Console MCP can take a snapshot of the actual button component, digging into the variants, the properties, the descriptions, and the annotations we attach to every component set. So I asked it to take another pass, this time against the real spec. It found the gaps between what it had assumed and what Figma actually defines, and it corrected them. Second pass matched the source.
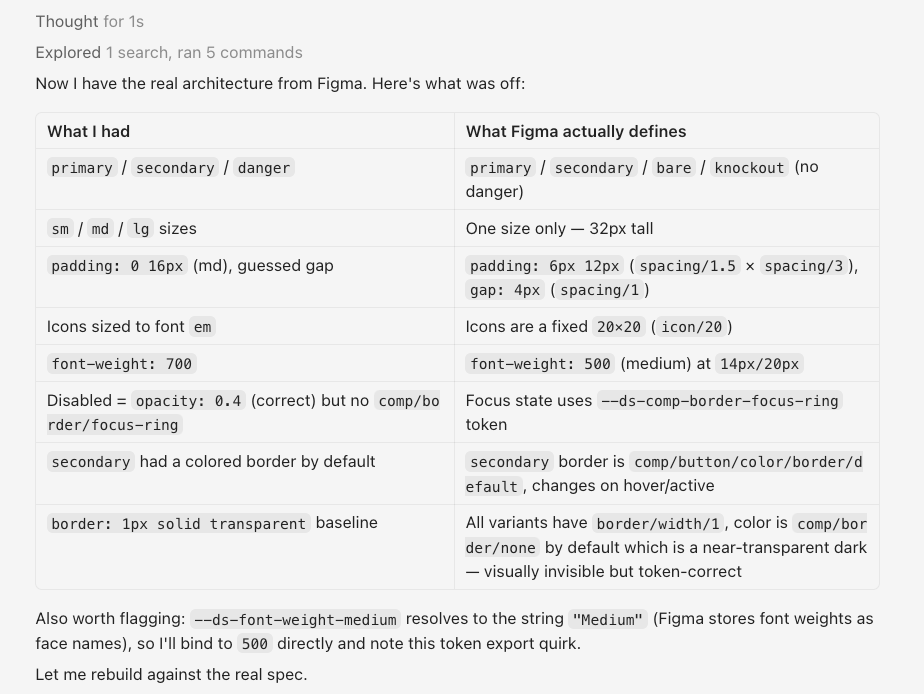
That gap-and-correction loop is not a failure of the workflow. It’s the workflow. The AI moves fast and sometimes overreaches; the structured context is what reins it in. The tooling is the net, not the whole catch.
Where this connects to Context-Based Design Systems
This is the part I keep coming back to. The reason the Greenfield setup works at all is that the context is engineered before the generation starts. The framework, the styling method, the icon set, the token source: all of it is established up front, so the AI is making decisions inside a defined space rather than inventing one.
When it did overreach on the button, the recovery wasn’t “try again and hope.” It was pointing it back at a real, structured source of truth and letting it reconcile. That only works if the source of truth exists and is legible to the model. Which is the entire premise: AI-readiness is just good design system hygiene, viewed from a different angle.


Next steps
This is now a full development environment, ready to go. The tokens are wired, Storybook is running, and the button matches its Figma source.
From here, the rule we follow is to start with primitives and work outward toward components with more dependencies and nesting. Build the foundation first, then the things that lean on it. The button was a happy accident this round, but the order matters once you’re past the first component.
That’s the Greenfield start. Empty folder to working, token-connected design system environment, with the AI doing the heavy lifting inside a context you defined. More on extending it in a future edition.


